Can generative AI test how two timber traditions converged?
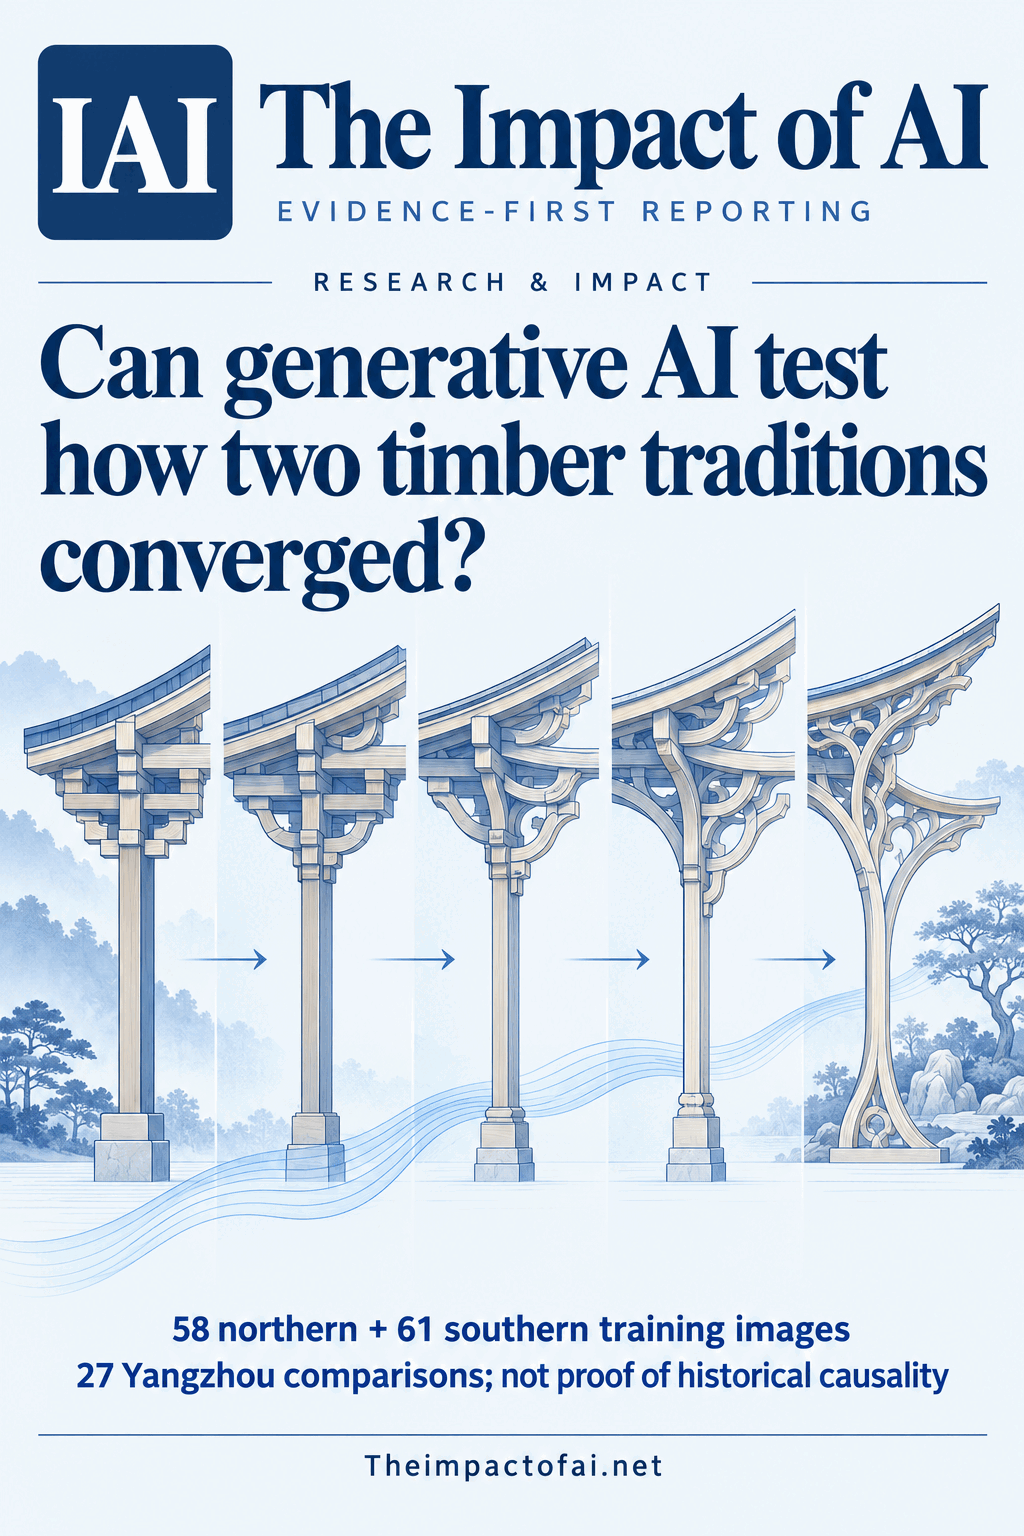
A peer-reviewed Chinese proof of concept fine-tunes two Stable Diffusion LoRA modules on 58 northern and 61 southern timberwork images, then compares controlled interpolations with 27 Yangzhou references. The middle of the model space resembles the usable historical samples, but this is compatibility—not proof of how history happened.
Editorial responsibility: The Impact of AI Editorial Desk · Report a factual concern
Research topic
Whether controlled dual-LoRA interpolation can model a formal spectrum between operational northern-official and southern-garden timbercraft endpoints and compare it with Qing-era Yangzhou canopy photographs
At a glance
- 1The endpoint datasets contained 58 northern and 61 southern images, split 52/6 and 55/6 for training and validation; 27 Yangzhou photographs were excluded from training and reserved for compatibility assessment.
- 2Five LoRA-weight settings produced 180 initial images before screening, with 154 retained for the main indicator analysis. A separate 30-image standardized batch was blindly rated by five domain experts.
- 3Twenty-five usable Yangzhou regions of interest sat closest to the middle 0.50–0.75 interpolation groups, but the design cannot establish historical transmission, constructional accuracy or conservation suitability.
The Impact Brief
Keep the evidence trail, not the noise.
Get the most consequential AI developments with direct sources and clear limits.
Living evidence record
Impact record IAI-1YN9XHT
Evidence stage
Studied
Confidence
Supported
Reporting basis
Source analysis
Independent support
Present
Record status
Monitoring
Last checked
3 October 2026
Source trail
1 direct source across 1 source type.
People impact
Documented in this record.
Uncertainty
Limits and next checks are explicit.
Stages describe the evidence available—not whether a technology is good or bad. See the public method.
Single-source reporting disclosure
This record analyses one direct source. It can establish what npj Heritage Science published or reported, but it is not independent corroboration of every performance claim or predicted outcome. The confidence label will change only when broader evidence is added.
A historical question turned into a controlled model
Interior timber canopies in Qing China combined structure, partition and ornament. Architectural history describes a northern official tradition associated with ordered frames and geometric motifs and southern Jiangnan garden work associated with lighter, more permeable and curvilinear forms. Yangzhou is a revealing case because court-linked production, salt-merchant wealth and movement between northern and southern craftsmen brought those traditions into contact. The researchers asked whether generative AI could turn that qualitative spectrum into controlled, measurable visual samples.
They did not claim that Stable Diffusion could recover lost buildings or recreate the path of cultural transmission. Instead, the paper defines two operational endpoints from selected images and semantic descriptions, trains a separate LoRA adapter for each and changes their relative weights across five alpha values from 0.00 to 1.00. Generated images are then measured for proportions, openwork, curve complexity, pattern density, decorative layering and a southern-tendency score. Historical Yangzhou photographs are compared afterwards to ask where they are compatible with this constructed space.[1]
What entered training—and what stayed outside
The northern prototype dataset contained 58 images, mainly palace interiors, official timberwork examples and documentary drawings. Fifty-two entered training and six validation. The southern prototype contained 61 images drawn from measured surveys and historical pictorial records of Jiangnan gardens; 55 entered training and six validation. Images were cropped, standardised to 512 by 512 pixels and annotated for structure, proportion, ornament, material and historical context. The authors also removed six Juanqinzhai images temporarily to test whether a partially hybrid palace source distorted the northern endpoint.
A separate set of 27 photographs from Ge Garden, He Garden and Wangshi Xiaoyuan in Yangzhou was excluded from endpoint training and parameter optimisation. After region-of-interest cropping, visibility checks and interference screening, 25 remained usable for the main comparison. That separation is an important strength: the historical cases were not used to teach the model what the desired intermediate should look like. Yet the endpoint collections remain small and source-imbalanced, and the selection and semantic labels encode the researchers' decisions about what counts as northern or southern.[1]
The generation experiment and its comparators
The team fine-tuned two LoRA modules on Stable Diffusion 1.5 while freezing the base model. The main configuration used rank 16, an effective batch size of eight and 12 epochs on an RTX 4090. Five alpha settings—0.00, 0.25, 0.50, 0.75 and 1.00—changed the balance between the northern and southern modules. Twelve standardised prompts and three fixed seed groups produced 36 initial images per alpha level, or 180 images. After predefined screening for collapsed structure, component disorder, semantic deviation and obstruction, the valid counts were 31, 30, 32, 30 and 31: 154 images in total.
The study also included a vanilla Stable Diffusion baseline using the same prompt and inference settings without either LoRA, and a revision-stage reproducibility check with retrained adapters. That standardized check held one prompt and six seeds constant across the five alpha levels, producing 30 images. Five domain experts with seven to 14 years of relevant experience rated the anonymised images from strongly northern to strongly southern. Consensus ratings rose with alpha, with a reported Spearman correlation of 0.785 and p below 0.001. Inter-expert agreement was moderate, not perfect, and the panel did not judge construction accuracy or historical plausibility.[1]
What the measurements found
Across the retained main-experiment images, higher southern weighting tracked a lower mean aspect ratio and upper-to-lower partition ratio, while openwork, curve complexity, pattern density, layering and the study's southern-tendency score increased. For example, mean openwork rose from 18.4% at alpha 0.00 to 35.8% at alpha 1.00, and mean southern-tendency score rose from 0.21 to 0.81. The groups differed significantly on all major indicators. Because alpha was deliberately set and the same model generated the images, those smooth trends demonstrate control within the constructed system rather than independent discovery of a natural law.
The 25 usable Yangzhou regions of interest sat closer to the middle of that modeled spectrum. Their mean aspect ratio of 1.14 fell between the 0.50 and 0.75 groups, and their mean openwork of 30.6% also lay near those intermediates. Principal-component projection and distance comparisons produced the same broad placement. A separate Huizhou control leaned more southern and did not repeat Yangzhou's central tendency, but it comprised one regional set and six standardized outputs. The authors correctly describe this as preliminary comparison, not proof that Yangzhou is unique.[1]
Why resemblance is not historical causality
The result is a compatibility statement: selected Yangzhou images share measured formal characteristics with generated images near the middle of two operational endpoints. It cannot show who transmitted a craft, which workshop changed a detail, how patronage shaped a commission or whether the same sequence occurred in time. The model's spectrum is created by mathematical mixing of adapters, while historical convergence involves people, materials, rules, geography and power. Documentary evidence, measured surveys and craft history remain necessary to explain those mechanisms.
Generative models add their own epistemic risk. They can invent joints, flatten culturally specific motifs, reproduce stereotypes from pretraining or make a structurally impossible canopy look persuasive. Two-dimensional pixels do not encode the three-dimensional logic of timber joints or constructability. The study's automatic descriptors are relative measures inside a shared image-processing setup, not absolute measurements of complex ornament. Curve complexity changed more under perspective perturbation than openwork, and segmentation or occlusion can alter the extracted values. These limits rule out using the outputs directly for conservation or construction decisions.[1]
Practical value, disclosures and the next test
Used cautiously, the method can help historians make an interpretive hypothesis visible, compare consistent descriptors and identify where archival or field research should concentrate. Museums and educators might use controlled counterfactuals to explain stylistic dimensions, provided every generated image is labelled and separated from authentic objects. Conservation teams could eventually use similar tools as one exploratory layer in a larger HBIM or rule-based workflow, but dimensions, joints and materials would have to be calibrated against surveys and checked by architectural historians, timber specialists and practitioners.
The research was funded by two Henan Province programmes; the authors say funders had no role and declare no competing interests. They disclose that Stable Diffusion 1.5 and author-trained LoRA modules generated image elements, while OpenAI Codex assisted in drafting plotting code that the authors ran and verified. The source datasets are not public because parts carry copyright and reuse restrictions, though they may be requested from the corresponding author. Confidence would rise with public derived data and code where lawful, source-balanced holdouts, larger independent expert panels, three-dimensional construction checks and replications across additional regions and building types.[1]
What this means for people
- Historians and heritage professionals gain a new hypothesis-testing aid, but still need authority to reject visually convincing outputs that conflict with material evidence.
- Museum visitors and students may understand stylistic variation more easily if synthetic examples are clearly labelled and never presented as surviving objects.
- Communities connected to the heritage should be involved when model categories simplify regional traditions or risk turning cultural difference into a generic visual slider.
Global context
This China-based study tackles a wider problem in digital heritage: generative systems can make interpretive categories visible, yet they can also erase provenance and construction knowledge. The method may transfer to other regions only after local experts define suitable evidence, categories and controls; a northern-to-southern Chinese spectrum is not a universal template for architectural culture.
What the evidence does not yet show
- The endpoint sets contain only 58 northern and 61 southern images, with uneven contributions from individual buildings and researcher-defined semantic labels.
- The 27 Yangzhou cases were properly excluded from training, but only 25 regions of interest remained usable and the comparison tests model-space compatibility rather than historical causation.
- Five experts rated 30 standardized generated images, but did not assess constructional accuracy, historical plausibility or Yangzhou compatibility.
- Generated two-dimensional imagery can hallucinate joints and motifs, inherit cultural stereotypes and cannot support conservation or construction decisions without independent evidence.
- Copyright restrictions prevent public release of the complete source-image dataset, limiting independent replication.
What to watch next
- Replication with larger, source-balanced and geographically broader image sets plus leave-one-building-out validation.
- Blind assessment of constructional accuracy, historical plausibility and regional compatibility by larger independent expert panels.
- Integration with measured geometry, joint typologies and archival records rather than direct conversion of generated images into conservation models.
Evidence trail
Sources used for this report
Links checked 3 October 2026
This report is labelled source analysis. We summarise and analyse source material in our own words; company statements remain attributed claims until independently supported. Translated summaries preserve the meaning of the original source and link back to it. Read our editorial standards.
Continue the story
Related reporting
Society & Media
Can image-aware AI catch fake news before it spreads?
A new peer-reviewed model improved two fixed benchmark tests by combining article text, images and an AI-generated image description. It did not verify claims or face a live, changing news stream.
7 min · 2 sources
Society & Media
Did AI-written petitions persuade more people to act?
A peer-reviewed natural experiment covering 1.5 million Change.org petitions found that access to an embedded AI writer changed language and increased similarity, but did not improve the engagement outcomes the researchers measured.
5 min · 2 sources
Society & Media
What do people actually ask image-upload AI to do?
An unreviewed Microsoft-led study analysed 42,617 de-identified Copilot image-upload sessions and checked its taxonomy against 23,413 ChatGPT sessions. Users often chained recognition into writing, code and data tasks—but private, model-generated summaries limit what outsiders can verify.
8 min · 2 sources
Reader discussion
Add evidence, experience or a question
No account is required. Reader notes are published after a brief civility, relevance and safety check; disagreement is welcome.
Published reader notes
0No published reader notes yet. You can start the evidence-led discussion above.
Prefer a private correction or response? Contact the newsroom.