Can sparse federated learning cut IoT communication without losing accuracy?
A peer-reviewed benchmark reports communication reductions of up to 477-fold for a hierarchical federated-learning method while remaining near strong accuracy baselines. The tests used stored sensor datasets and simulated client hierarchies—not a live device fleet or a privacy audit.
Editorial responsibility: The Impact of AI Editorial Desk · Report a factual concern
At a glance
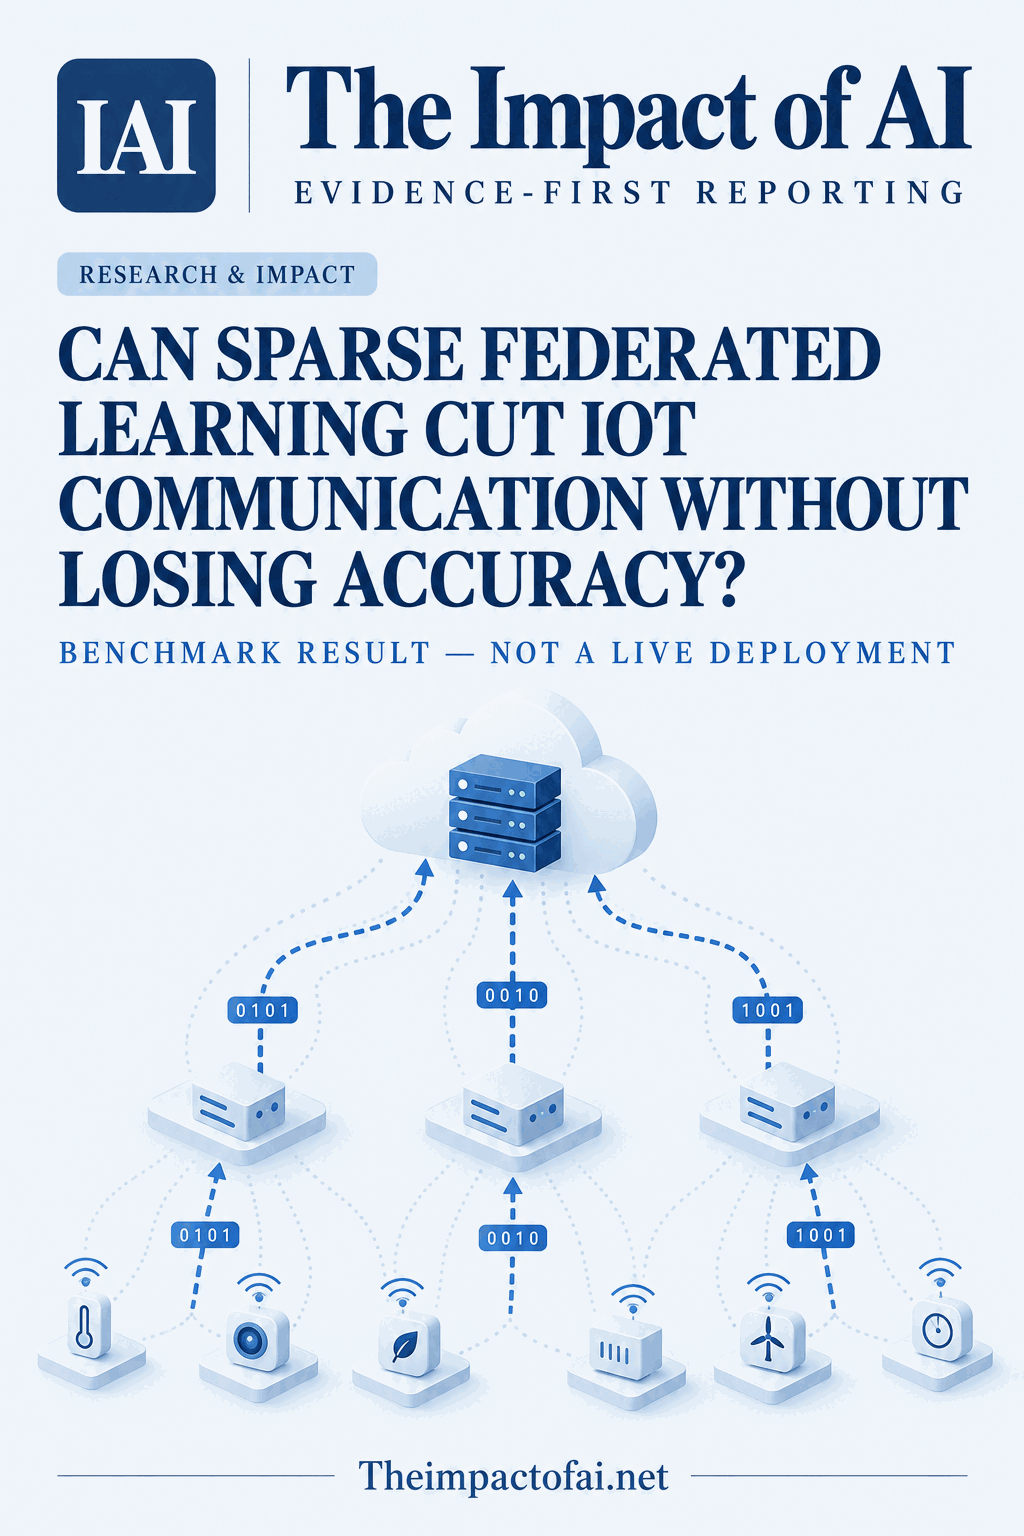
- 1H-FedSN sends learned binary masks while keeping original network weights frozen, combines shared and local personalised layers, and aggregates masks through edge and cloud tiers.
- 2The authors compared the method with six adapted baselines on MNIST and three sensor datasets: WISDM smartwatch, WIDAR Wi-Fi gesture and WISDM phone activity data.
- 3The largest communication advantage depends on the baseline and configuration; the work is an offline benchmark, not proof of latency, energy, privacy or reliability on deployed IoT hardware.
Research topic
Hierarchical federated learning for IoT
The direct answer: the benchmark says yes, with important trade-offs
H-FedSN cut the number of bytes communicated per training round by one to two orders of magnitude while keeping classification accuracy close to strong personalised federated-learning baselines in the authors' experiments. Its largest reported reduction was 477-fold relative to a baseline under one tested setting. On the clearest small hierarchy—two edge servers with five clients each—the method used 252.94 KB per round on MNIST versus 60,414.31 KB for hierarchical federated averaging, while accuracy was 99.36% versus 99.68%.
That is a meaningful engineering result, not a universal ratio. The denominator changes with model, dataset, topology and comparator. The experiments replayed stored datasets under constructed non-independent client distributions; they did not install software across watches, phones, buildings or industrial gateways. The paper therefore supports a benchmark claim about exchanging compact model masks, not a production claim about network latency, battery life, privacy attacks or sustained operation.[1][2]
What H-FedSN sends through the hierarchy
Conventional federated learning keeps raw records on participating devices but repeatedly exchanges model updates. In a hierarchical system, clients send updates to nearby edge servers, which aggregate them before a cloud tier combines the edge results. That structure can fit device networks better than every client contacting one server, yet full parameter updates remain expensive and uneven client groups can distort the model.
H-FedSN freezes a common neural network's original weights and learns a binary mask that determines which connections remain active. Shared mask layers are aggregated through the hierarchy; personalised layers stay with each client to adapt to local data. At edge and cloud tiers, cumulative Beta distributions turn incoming binary decisions into probability masks. The design reduces transmitted values and tries to prevent a large or unusual client group from dominating purely through conventional averaging.[1][2]
Four datasets and six comparators
The evaluation used MNIST as a general image-classification benchmark and three sensor datasets. WISDM smartwatch data contains accelerometer and gyroscope recordings of 18 daily activities from 51 participants. WIDAR contains Wi-Fi-derived signals from 17 participants performing 22 gestures. A separate WISDM phone dataset provided another activity-recognition task. These are real recorded datasets, but the networking, client assignment and training hierarchy were experimental constructions.
Six baselines were adapted to the same hierarchical architecture: ESPerHFL and HierFAVG, the personalised methods FedPer and FedRS, and the communication-oriented methods FedCAMS and TOPK. Experiments included small, larger and imbalanced client layouts. That comparison is broader than a single favourite baseline, but it remains the authors' implementation and hyperparameter design. Independent reproduction on the same splits is needed before treating the ranking as stable.[1][2]
Reading the accuracy–communication trade-off
In the two-edge, five-client setting, H-FedSN used 121.88 KB per round on WISDM smartwatch data and reached 74.42% average accuracy. FedRS reached 75.97% but communicated 7,084.38 KB—about 58 times as much. On WIDAR, H-FedSN reached 76.37% at 264.75 KB, while FedPer reached 82.85% at 36,136 KB. On WISDM phone data, H-FedSN reached 42.98% at 121.88 KB; FedPer reached 48.36% at 6,988 KB.
Those figures make the central result more precise than ‘without losing accuracy’. The method did lose some accuracy against the strongest personalised comparator on several tasks, sometimes by more than five percentage points, while greatly reducing communication. Against the communication-optimised baselines, the paper reports better average accuracy and lower communication across the tested settings. The practical question is therefore whether an application's bandwidth constraints justify the residual performance gap, not whether efficiency is free.[1][2]
Why the 477-fold headline needs context
The peer-reviewed Article in Press says communication was reduced by up to 477 times relative to baseline methods. The earlier December 2024 preprint described a 58- to 238-fold range against HierFAVG. The difference is not evidence that the old preprint was newly published; it shows that the accepted paper's experiments and framing evolved. The 8 October date belongs to the peer-reviewed Article in Press, while the manuscript's public history began much earlier.
Per-round communication is also only one part of system cost. The paper reports that methods approached convergence around 20 rounds in the small configuration, but a deployment must count the total number of rounds, client computation, memory, radio wake time, retransmissions and server work. A compact update can still be slow over unreliable links, and a frozen random-weight network with learned masks may impose local computation that different hardware handles unevenly.[1][2]
Privacy is an architecture property, not a result here
Federated learning avoids collecting raw training records in one place, but that does not make a system automatically private or secure. Model updates can leak information, malicious clients can poison aggregation, personalised layers can preserve sensitive patterns, and edge servers introduce additional trust boundaries. The study measured classification accuracy and communication cost; it did not present a differential-privacy guarantee, a secure-aggregation protocol, an attack evaluation or a regulatory assessment.
For organisations considering connected-device learning, the useful lesson is narrower: binary masks may be an efficient update representation worth testing when data and clients are highly heterogeneous. A responsible pilot would measure accuracy by subgroup and device, total energy, connection failures and attack resistance, while defining which tier can see which update. It would also compare the method against simply training less often, using smaller conventional models or centralising consented data where that is lawful and operationally simpler.[1][2]
Evidence limits and what would change the assessment
The sensor records are genuine, but the paper reports offline machine-learning experiments rather than a field trial. WISDM and WIDAR are activity and gesture benchmarks with limited participant counts; they do not represent the diversity, failure modes or network conditions of global IoT fleets. Accuracy is an aggregate classification metric, and communication is estimated in transmitted kilobytes per round. There is no direct measurement of wall-clock latency, battery drain, hardware memory, packet loss, privacy leakage or lifecycle maintenance.
Confidence would rise with independent reproductions, tests on deployed heterogeneous hardware and end-to-end measurements under intermittent networks. Privacy and poisoning audits should accompany communication benchmarks, and comparisons should report total training cost rather than only a favourable round. The research was funded by US National Science Foundation grant 2217071, Stanford's Center for Sustainable Development and Global Competitiveness, and the Yonghua Foundation. The authors declared no competing interests. The Article in Press is peer reviewed and citable but may still receive editorial corrections before the final version of record.[1][2]
What this means for people
- Device users could benefit if learning updates use less bandwidth and energy, but those benefits were not measured here.
- Deployers must decide whether the observed accuracy gaps are acceptable for a particular task and population.
- Keeping raw data on devices reduces central collection but does not by itself guarantee privacy or security.
Global context
Hierarchical federated learning is relevant wherever large device fleets connect through local gateways before cloud services, from consumer sensors to industrial systems. Network cost, device capability, regulation and threat models vary sharply across regions. A method that works on US-hosted benchmark data still needs local validation, especially where connectivity is intermittent or decisions affect health, safety or access to services.
What the evidence does not yet show
- The work is an offline benchmark using stored datasets and constructed client hierarchies, not a live IoT deployment.
- Communication cost is reported per round; latency, energy, memory, packet loss and total convergence cost were not directly established on devices.
- H-FedSN remained below the strongest personalised baseline on several accuracy comparisons, so the efficiency gain is not cost-free.
- The study did not provide a differential-privacy guarantee, secure-aggregation evaluation or adversarial attack test.
- The sensor datasets include limited participant populations and tasks that may not generalise to industrial, medical or public infrastructure.
- The accepted Article in Press is peer reviewed and citable but subject to further editorial changes.
What to watch next
- Independent reproduction of the 477-fold maximum and the accuracy trade-offs.
- End-to-end trials on heterogeneous devices with measured energy, latency and packet loss.
- Privacy leakage, poisoning and edge-server compromise tests.
- Total communication and computation through convergence, not only per-round traffic.
Living evidence record
Impact record IAI-1V6IJ1C
Evidence stage
Studied
Confidence
Supported
Reporting basis
Multi-source analysis
Independent or research support
Present
Record status
Monitoring
Last checked
8 October 2026
Source trail
2 direct sources across 1 source type.
People impact
Documented in this record.
Uncertainty
Limits and next checks are explicit.
Stages describe the evidence available—not whether a technology is good or bad. See the public method.
Evidence trail
Sources used for this report
Links checked 8 October 2026
This report is labelled multi-source analysis. We summarise and analyse source material in our own words; company statements remain attributed claims until independently supported. Translated summaries preserve the meaning of the original source and link back to it. Read our editorial standards.
Continue the story
Related reporting
Technology
Can outsiders verify how Gboard uses training data?
Google says a new server-side federated-learning system lets auditors inspect which programs may process encrypted device data. A company preprint reports larger device coverage and a live test on 7 million devices, but independent reviewers have not yet tested the end-to-end guarantee or the trusted hardware beneath it.
10 min · 3 sources
Technology
Cloud offloading could change the performance and battery trade-off for robots
Microsoft Research reports that moving some physical-AI inference from a robot's onboard processor to edge or cloud GPUs can improve task success, efficiency and the complexity of workloads the machine can handle.
2 min · 1 source
Technology
Can a smaller AI model separate voices from noise in real time?
A 3.9-million-parameter model separated overlapping speech and suppressed noise with competitive open-benchmark scores at lower computational cost. It ran faster than real time on one CPU core, but reverberation reduced performance and no live hearing, conferencing or call-centre deployment was tested.
6 min · 1 source
The Impact Brief
Keep the evidence trail, not the noise.
Get the most consequential AI developments with direct sources and clear limits.
Reader commentary
Add evidence, experience or a question
No account is required. Reader notes are published after a brief civility, relevance and safety check; disagreement is welcome.
Explore commentary across the portal →Published reader notes
0No published reader notes yet. You can start the evidence-led discussion above.
Prefer a private correction or response? Contact the newsroom.